Fintech · Platform Reliability · 17 min
Designing Reliable Asynchronous Workflows in Fintech: Retries, Idempotency, Reconciliation and Auditability
A practical way to reason about retries, duplicate prevention, reconciliation and support visibility when financial workflows cross services.
By Haziq Hasan · Application Modernization Engineer
Published 27 September 2026
Meet the Xyncwave team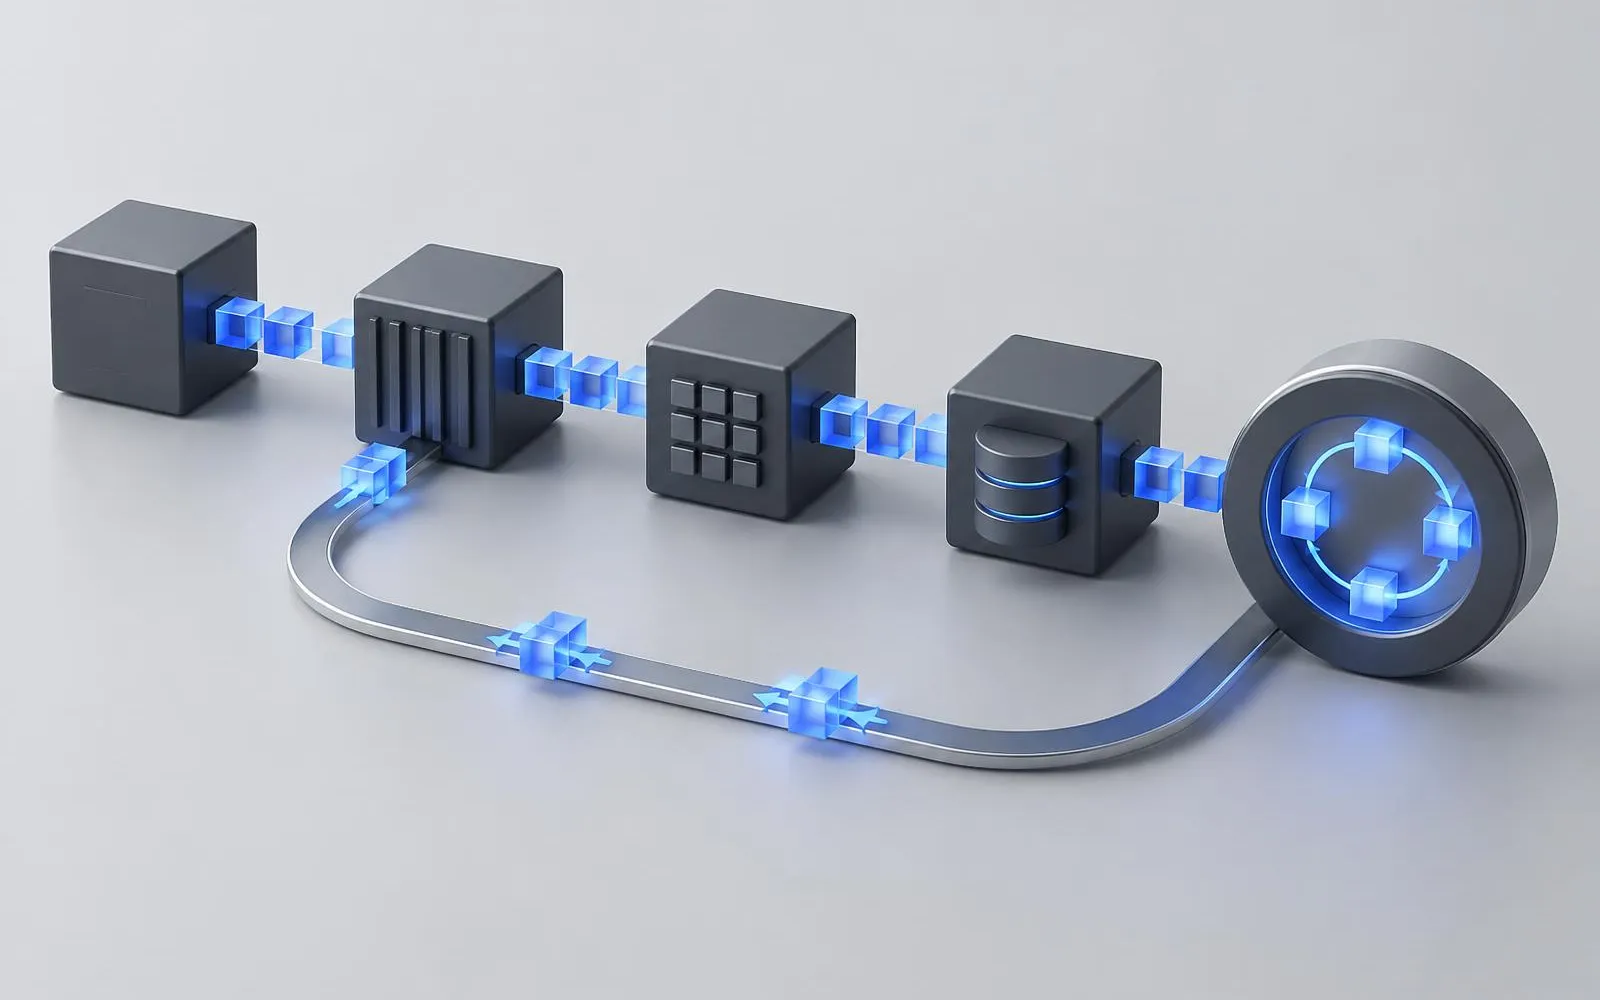
Direct answer
What makes an asynchronous fintech workflow reliable?
When work is long-running, dependent on a provider or safe to complete after the original request, persist the intent before processing it asynchronously. Explicitly design state ownership, idempotency, bounded retries, failed-message handling, reconciliation, audit records and observability. A queue alone does not make a financial operation correct.
Key takeaways
- Acknowledge receipt only after intent has been durably recorded.
- An idempotent retry must not repeat the business effect.
- Differentiate transient failures from invalid business states.
- Reconcile internal and external states rather than assuming they always agree.
- Make every transition explainable to support and operations.
The Reliable Async Workflow
Accept → Persist Intent → Queue/Event → Process → Validate → Persist Result → Reconcile → Notify / Continue.
At acceptance, record a unique operation identifier and the intended action before telling the customer that work is underway. Queue or publish the task after that durable record exists; otherwise an interruption can leave a customer-facing acknowledgement with no recoverable work. Processing reads the current state, performs the allowed action, validates the response, persists the result and advances a state machine.
Notification follows persisted truth rather than preceding it. Supporting controls—idempotency, retry, audit and monitoring—span the entire chain. This is a design lens, not a claim about the private implementation of any published case study.
A reliable workflow begins before a message reaches a queue. Record the business intent with a stable identifier and an initial state, then make the subsequent work discoverable and repeatable. Otherwise an accepted customer request may exist only in memory while a worker is waiting to run. Sketch the state transitions in plain language: accepted, awaiting provider, confirmed, rejected, requires investigation. For every transition, name the event or evidence that permits it and the team that can intervene when it stalls.
Do not promise immediate completion when a third party has not confirmed it. An acknowledgement means the request was received; it is not the same as an external settlement or completed order. The interface should show a truthful intermediate state and a way for support to locate it. The choice of queue or event service is secondary to a recoverable record of what was requested, what has already happened and what may happen next.
Document state transitions in a table before choosing infrastructure. For each transition, specify the current state, required event, action to persist, external dependency and possible next states. Add an explicit branch for unknown outcomes. A timeout from a provider is not automatically a rejection; an accepted operation may simply lack its acknowledgement. A transition table lets engineers write tests for late events and lets operations decide when to investigate. It also prevents the interface from treating a queue acknowledgement as final completion.
Make the correlation reference available through the whole journey. The reference should connect a customer request to processing attempts, provider acknowledgements and support investigation, while not exposing secrets in logs or customer-facing URLs. When a transaction is resubmitted after a browser refresh, the platform can locate the existing intent rather than generate a second one. The exact storage and expiry design depend on the business action and provider behavior; what matters is preserving identity across retries and recovery.
- 01Accept
- 02Persist Intent
- 03Queue / Event
- 04Process
- 05Validate
- 06Persist Result
- 07Reconcile
- 08Notify / Continue
Choose the response boundary deliberately
Keep immediate checks synchronous; move work that can safely finish later behind an explicit pending state.
A login decision, input validation or immediate authorization response may need to finish in the request. A provider-dependent reconciliation or report preparation may not. The question is whether the user needs the final result now, and whether the business action can be represented truthfully as pending.
A pending response is not a successful settlement or completed trade. Name states in language users and support staff can understand: accepted, processing, completed, rejected or requires review. Avoid a generic success flag while another system still owns the final decision.
Keep synchronous steps for decisions the caller genuinely needs before proceeding: authentication, input validation or determining whether the request can be accepted. Long-running processing and external callbacks can continue asynchronously, but the customer-facing journey still needs a response. Return a stable reference that can be used to check status. Agree whether the user may cancel, retry or edit while processing, and ensure the system enforces those rules rather than relying on button states alone.
Design for the ambiguous timeout. If the client sees no response, it cannot know whether the server accepted the request. Its retry must carry the same business-intent identifier; the server must return the existing state if the request was already recorded. Testing only a clean success and a clean rejection misses the most important path: the action may have succeeded while the response was lost.
Prevent retries from multiplying business effects
Idempotency means repeating the same request does not unintentionally repeat the action.
Assign an operation key at the business boundary, not just a transport-message ID. Store the relationship between that key, the attempted action and the final or pending outcome. On a duplicate request, return the recorded state or resume safe work instead of creating another payment, instruction or ledger update.
Idempotency has a scope: the key must identify the same intended action with compatible parameters. Decide when keys expire and how conflicts surface. A provider's API idempotency key protects its own boundary; your platform must still protect its internal state transitions and notifications.
Idempotency means a repeated delivery of the same intent does not repeat its business effect. Define its scope explicitly: which customer, action, payload and period does one key represent? A matching key with changed payment details should not silently inherit the result of a different request. Store the identifier alongside the durable intent and return a consistent status for retries. Provider-side idempotency can help at an API boundary, but it does not replace protection of your own state transitions and records.
Test duplicate arrival at several points: before work starts, while a worker is still processing, after a provider call succeeds and after notification fails. The correct response can differ at each stage. A duplicate might wait for the in-progress result; a post-completion retry should report the result already recorded; a failed notification may be retried without repeating the underlying financial action. This is why deduplication must be tied to the business operation, not only to queue delivery.
Retry only when the failure can recover
Transient timeouts differ from rejected business requests, unavailable providers and invalid state transitions.
For a temporary network fault, use bounded attempts with spacing and a visible retry status. A permanent validation failure should become a reviewed rejection, not an endlessly repeated message. A provider outage may need a circuit breaker or delayed recovery. A business-state conflict requires a new decision about the operation, not blind replay.
Send exhausted or malformed tasks to a failed-processing path with context and a safe replay procedure. A dead-letter queue is not a trash bin: someone must own investigation, correction and evidence of the replay. Ordering matters too. A later notification failure must not undo an earlier completed business action; it should create a distinct recoverable task.
Classify failures before choosing retries. A temporary network error may warrant a bounded retry with delay; invalid account details require correction; an ambiguous provider timeout may require status lookup before any repeat; an unauthorized request must stop. Record the attempt and its response without treating every error as a new business request. A failed-processing queue is only useful if an operator can identify the intent, reason, last safe state and permitted recovery action.
Event ordering matters. A later notification failure should not turn a confirmed transaction back into an unconfirmed one. Separate core business states from side effects and define transitions that cannot be reversed by a late callback. Where an external system can send messages out of order, compare event sequence or authoritative state rather than simply accepting the last message received. Recovery should restore the correct state, not merely clear a queue.
Run failure-injection exercises in a non-production setting. Stop a worker after a provider accepts an action but before the local result is recorded; delay a callback; send the same event twice; change their order. For each, write down the expected state, whether the worker may retry and what an operator sees. If the team cannot agree, there is a business-rule gap, not merely a missing retry library. A test that catches this disagreement before launch is itself a useful architectural outcome.
Interactive planning tool
Critical Workflow Review
Test one async journey against the controls it actually needs.
Is customer intent durably recorded before processing?
Reconcile across boundaries and keep an audit trail
Two systems may disagree temporarily; the design should say who is authoritative and how discrepancies are resolved.
Record external references, timestamps, request identity and meaningful transitions so an operator can answer what was accepted, sent, confirmed, retried and escalated. Reconciliation compares the platform's recorded result with an authoritative external or downstream record and puts discrepancies into a review workflow. Do not silently force a match.
Instrument each stage with a correlation identifier, actionable error categories and alerts that distinguish processing delay from actual loss. The digital stock brokering platform case study documents asynchronous/serverless processing and production troubleshooting among its engineering disciplines. It does not publish private transaction mechanics; use it as context for the reliability questions, not as a claim of a particular design.
Reconciliation compares what the platform believes happened with evidence from other participants. Choose a stable reference shared across systems, define expected timing and put disagreements into named exception categories. A missing provider confirmation, a duplicate callback and a mismatch in amount need different investigation paths. Reconciliation is not a single nightly script; it is an operating responsibility with ownership, review cadence and a documented route for correcting records without hiding the original event.
For support and engineering, connect logs, traces and business events through a correlation identifier while controlling access to sensitive details. A useful case view answers when a request was accepted, which stage last completed, what was attempted, what the provider returned and whether the current state has been reconciled. The brokerage case study documents connected platform and cloud/serverless processing capabilities; it is a relevant architectural context, not a claim about a specific undisclosed retry policy or transaction volume.
Walk through a lost-response scenario with the product and operations teams. A customer submits a request; the server records it and sends work to a processor, but the browser times out before receiving the acknowledgement. The customer retries. The platform should recognize the original intent, show its current state and avoid a second business effect. Then suppose the provider accepted the action but its callback is delayed. The platform must not equate missing callback with confirmed failure. It can check provider status or place the request in investigation, depending on the provider contract.
Now test the recovery route. An operator receives an exception showing the internal reference, external reference if available, last successful step and the exact disagreement. Can the operator tell whether a retry is safe? Can they link a manual correction to the original request rather than overwriting history? Can support explain the state to the customer without exposing internal error details or implying completion too early? These questions determine what to log and what tooling to build. They are far more informative than a demonstration in which every service responds on time.
Finally decide what 'done' means for the journey. A processor may complete its step before a downstream report or notification is updated. Define which transition is customer-facing completion, which side effects can lag and how long an unresolved item is allowed to remain before escalation. Keep those time windows as product and provider-specific decisions rather than adopting an invented universal threshold. A reliable asynchronous architecture makes those distinctions visible and testable.
Buyer questions
Frequently asked questions
Evidence register
Research & Sources
- 01Stripe Docs, n.d.: Idempotent requests
A concrete illustration of duplicate-safe API requests; application semantics still need separate design.
- 02Microsoft Learn, n.d.: Retry pattern
Distinguishes transient faults from failures that should not be retried.
- 03AWS Docs, n.d.: Amazon SQS dead-letter queues
A vendor example of isolating failed messages for investigation.
- 04OpenTelemetry, n.d.: Observability primer
Guidance on correlating telemetry across services.
Walk one critical workflow from intent to recovery.
Bring the states, dependencies and failure mode of one product journey. Review the controls before adding another queue or service.
Review a Critical Fintech Workflow